It’s 2 AM and Your Database Just Got Nuked
Your phone is blowing up. The on-call alert says production is “acting weird.” You SSH in and find the evidence: a junior dev ran a migration script that executed DELETE FROM orders WHERE status = 'pending' — the WHERE clause silently failed on a typo, and it wiped the entire orders table. 47,000 rows. Gone.
That’s exactly where pg_dump backups fail you. Your last dump was 6 hours ago. That’s 6 hours of orders, payments, and customer data you can’t recover from a traditional snapshot. But with Point-in-Time Recovery (PITR) set up via pgBackRest, you’d be back online in 20 minutes — restored to exactly one minute before the bad migration ran.
Here’s how to build it before that incident happens.
Why pg_dump Isn’t Enough for Production
Traditional pg_dump creates a snapshot — a full copy of your database at a single moment. It works fine for small databases or dev environments. In production, it has two fatal problems:
- High RPO (Recovery Point Objective): You lose all data between your last dump and the incident. Dump every 6 hours, lose up to 6 hours of data.
- No time-travel: You can only restore to the exact moment the dump ran. There’s no “restore to 5 minutes before the bad query.”
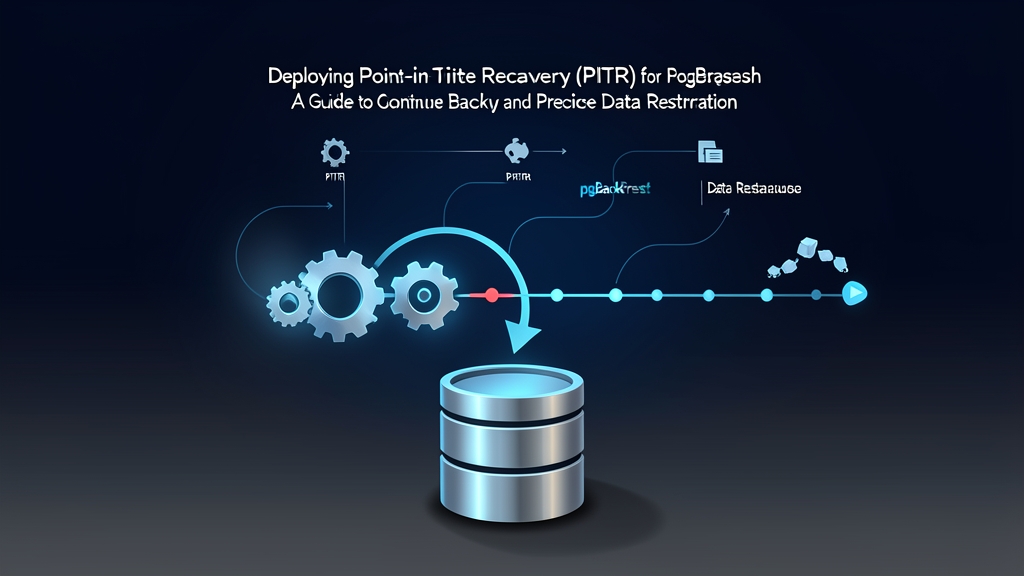
PITR solves both by continuously archiving WAL (Write-Ahead Log) files. PostgreSQL writes every change to WAL before applying it to data files. Preserve those WAL files and you can replay transactions up to any exact timestamp.
pgBackRest makes this production-ready. Full, differential, and incremental backups are all built in. WAL archiving runs automatically in the background. Restores run in parallel — a 300GB database that takes 25 minutes single-threaded finishes in roughly 8 minutes with 4 workers. Every backup file gets a checksum, and storage can be local disk, S3, or Azure Blob Storage. It’s the de-facto standard for serious PostgreSQL deployments.
Setting Up pgBackRest: Step by Step
These steps target Ubuntu 22.04 with PostgreSQL 15. Adjust paths for your version.
Install pgBackRest
sudo apt-get update
sudo apt-get install pgbackrest -y
pgbackrest version
Create the Configuration File
sudo mkdir -p /etc/pgbackrest
sudo nano /etc/pgbackrest/pgbackrest.conf
[global]
repo1-path=/var/lib/pgbackrest
repo1-retention-full=2
log-level-console=info
log-level-file=detail
[main]
pg1-path=/var/lib/postgresql/15/mainEnable WAL Archiving in PostgreSQL
Edit postgresql.conf:
sudo nano /etc/postgresql/15/main/postgresql.confAdd or update these settings:
wal_level = replica
archive_mode = on
archive_command = 'pgbackrest --stanza=main archive-push %p'
archive_timeout = 60
max_wal_senders = 3
The archive_timeout = 60 line is critical. Without it, WAL segments only archive when they fill up to 16MB — on a low-traffic database that could mean hours between archives. Setting 60 seconds means you archive at least every minute, giving you a 60-second RPO in the worst case.
sudo systemctl restart postgresqlInitialize the Stanza and Take Your First Backup
sudo -u postgres pgbackrest --stanza=main stanza-create
sudo -u postgres pgbackrest --stanza=main --type=full backup
Once the full backup completes, pgBackRest takes over WAL archiving continuously. Your RPO drops to near-zero from that point forward. Schedule automated backups in cron:
# Daily full backup at 1 AM
0 1 * * * postgres pgbackrest --stanza=main --type=full backup

# Differential backup every 6 hours
0 */6 * * * postgres pgbackrest --stanza=main --type=diff backup
The Actual Recovery: Restoring to a Point in Time
Here’s the part that matters at 2 AM. First, find the approximate timestamp when things went wrong. Check your application logs, PostgreSQL logs, or ask the dev what time the migration ran. Say the bad deletion happened at 2024-11-15 02:03:00 UTC.
Stop PostgreSQL and Clear the Data Directory
sudo systemctl stop postgresql
sudo -u postgres find /var/lib/postgresql/15/main -mindepth 1 -delete
Restore to One Minute Before the Incident
sudo -u postgres pgbackrest --stanza=main restore \
  --target="2024-11-15 02:02:00+00" \
  --target-action=promote \
  --type=time
The target is 02:02:00 — one minute before the bad query. That precision is the whole point of PITR. Under the hood, pgBackRest locates the most recent full backup that predates your target timestamp, restores those data files, then replays WAL segments one by one until it hits your cutoff and stops.
Start PostgreSQL and Verify
sudo systemctl start postgresql
sudo -u postgres psql -c "SELECT count(*) FROM orders;"
If you see 47,000 rows, you just saved the company. Total downtime: under 20 minutes.
Monitoring — Because a Broken Archive Is Worse Than No Archive
Never assume the archive is healthy — check it actively and often:
sudo -u postgres pgbackrest --stanza=main infoLook for status: ok and confirm the WAL archive min/max is advancing over time. If you see status: error, your PITR is silently broken.
PostgreSQL’s own stats view tells the same story:
sudo -u postgres psql -c "SELECT last_archived_wal, last_failed_wal, failed_count FROM pg_stat_archiver;"If failed_count is climbing, your archive command is broken and you need to fix it immediately — not in the morning, now.
Once a month, spin up a staging server and run a full restore. Verify row counts, spot-check your most critical tables. I got burned once trusting a backup that had two weeks of archive gaps — a permissions change broke the archive_command silently and nothing alerted on it.
A Few Gotchas Worth Knowing
Some things I learned the hard way:
- Disk space: WAL files accumulate fast on busy databases. Set
repo1-retention-archive-type=incrto automatically clean old archives aligned with your retention policy. - Permissions: Run all pgBackRest commands as the
postgresuser. Mixing root and postgres ownership causes confusing failures. - Test before you need it: Never run your first restore during an actual incident. Walk through the restore process on staging at least once so muscle memory kicks in at 2 AM.
- Validate imports before they hit the database: The best recovery is one you never need. Before any bulk data import, validate the structure first — when it’s CSV, run it through toolcraft.app/en/tools/data/csv-to-json to inspect the shape before it touches Postgres (browser-only, no data leaves your machine). Catching a malformed import at that stage beats a PITR restore every time.
Where PITR Fits in a Complete Backup Strategy
Point-in-Time Recovery handles the “someone deleted production data” scenario well. What it doesn’t cover:
- Offsite storage: Configure
repo1-type=s3to push backups to S3. Disk failures happen and they don’t respect your backup schedule. - Streaming replication: Protects against hardware failure, but won’t protect against logical errors — a bad DELETE replicates immediately to standby servers.
- Periodic pg_dump exports: Keep weekly logical backups for portability. Schema migrations sometimes require a clean dump, not a file-level restore.
Stack all three — pgBackRest PITR, streaming replication, weekly pg_dump exports — and you’ve covered almost every failure mode production can throw at you. Each layer catches what the others miss.
Get it running before you need it. Walk through a full restore on staging at least once, so when it actually is 2 AM and you’re half-awake, the commands are muscle memory — not something you’re Googling under pressure.