When a Simple JOIN Isn’t Enough
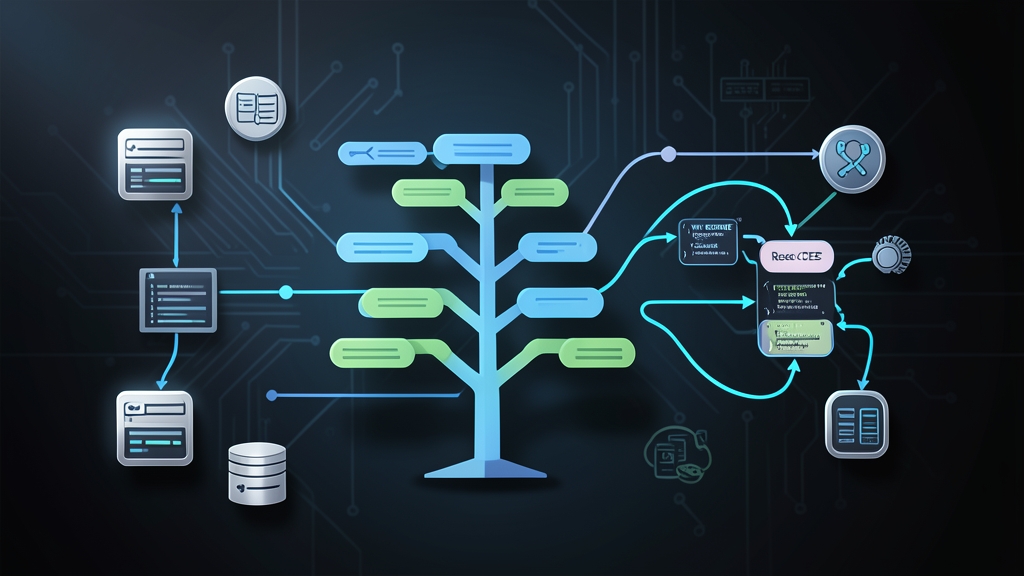
You’re building an e-commerce platform. The product categories look like this:
Electronics
  └── Phones
        ├── Android
        └── iPhone
  └── Laptops
        └── Gaming Laptops
Your first instinct is to use a self-join. You write one JOIN for the first level, another for the second — and then you realize the data can go five levels deep. Suddenly you’re writing eight JOINs for a query that should be three lines.
This is the classic hierarchical data problem. It shows up in product categories, org charts, file systems, permission inheritance, comment threads — anywhere structure nests inside structure. Standard relational SQL wasn’t originally designed for recursive structures, but modern databases solved this cleanly with Recursive CTEs.
Core Concepts
The Adjacency List Model
The most common way to store hierarchical data is the adjacency list model: each row stores a reference to its parent. Here’s a categories table using this pattern:
CREATE TABLE categories (
    id        INT PRIMARY KEY,
    name      VARCHAR(100) NOT NULL,
    parent_id INT REFERENCES categories(id)  -- NULL means root node
);
Simple to understand and easy to insert new nodes. The challenge is reading it back as a tree — that’s where the recursive part comes in.
What Is a Recursive CTE?
A CTE (Common Table Expression) is a named subquery you define at the top of your SQL with the WITH keyword. A recursive CTE is one that references itself, letting the query loop level by level until there’s nothing left to process.
The structure always has two parts joined by UNION ALL:
- Anchor member: The starting point — your base case (the root node, or whichever node you want to start from)
- Recursive member: Joins back to the CTE itself, stepping one level deeper each iteration
The database keeps running the recursive member until it returns no new rows. No application-side loop needed.
Hands-On Practice: Category Tree
Step 1: Set Up the Data
Let’s create a category tree and insert some test data. I’ll use PostgreSQL syntax — MySQL 8+ uses the same WITH RECURSIVE keyword; SQL Server supports recursive CTEs too but drops the RECURSIVE word entirely:
INSERT INTO categories (id, name, parent_id) VALUES
    (1, 'Electronics',    NULL),
    (2, 'Phones',         1),
    (3, 'Laptops',        1),
    (4, 'Android',        2),
    (5, 'iPhone',         2),
    (6, 'Gaming Laptops', 3),
    (7, 'Samsung',        4),
    (8, 'Pixel',          4);
Step 2: Fetch All Descendants of a Node
Say you want every category under “Electronics” (id = 1). Here’s the recursive CTE:
WITH RECURSIVE category_tree AS (
    -- Anchor: start at the root node
    SELECT id, name, parent_id, 0 AS depth
    FROM categories
    WHERE id = 1

    UNION ALL

    -- Recursive: join children to the current result set
    SELECT c.id, c.name, c.parent_id, ct.depth + 1
    FROM categories c
    INNER JOIN category_tree ct ON c.parent_id = ct.id
)
SELECT id, name, depth
FROM category_tree
ORDER BY depth, name;
Result:
 id | name             | depth
----+------------------+-------
  1 | Electronics      |   0
  2 | Phones           |   1
  3 | Laptops          |   1
  4 | Android          |   2
  5 | iPhone           |   2
  6 | Gaming Laptops   |   2
  7 | Pixel            |   3
  8 | Samsung          |   3
The depth column is free to track — it costs nothing and tells you exactly how many levels deep each node sits.
Step 3: Build the Full Breadcrumb Path
Breadcrumb strings like “Electronics > Phones > Android” are a common requirement. Adjust the CTE to accumulate the path as a string while it traverses:
WITH RECURSIVE category_path AS (
    -- Anchor: root nodes, path starts with just their name
    SELECT id, name, parent_id, name::TEXT AS path
    FROM categories
    WHERE parent_id IS NULL

    UNION ALL

    -- Recursive: append child name to the existing path
    SELECT c.id, c.name, c.parent_id, cp.path || ' > ' || c.name
    FROM categories c
    INNER JOIN category_path cp ON c.parent_id = cp.id
)
SELECT id, name, path
FROM category_path
ORDER BY path;
This generates a clean breadcrumb string for every node in the tree — no application-level looping, no extra queries.
Real-World Use Case: Multi-Level Role Permissions
Permission inheritance is the other place this pattern earns its keep. Take a role hierarchy where each role extends from a simpler base:
Viewer        (base: can view)
  └── Editor  (adds: can edit)
        └── Manager  (adds: can publish)
              └── Admin  (adds: delete, manage users)
Each role owns only its unique permissions. A Manager logging in should automatically get everything an Editor and Viewer can do. You need to climb up the inheritance chain to collect everything they’ve accumulated.
Setting Up the Roles and Permissions Tables
CREATE TABLE roles (
    id        INT PRIMARY KEY,
    name      VARCHAR(50) NOT NULL,
    parent_id INT REFERENCES roles(id)  -- points to the simpler base role
);

CREATE TABLE role_permissions (
    role_id    INT REFERENCES roles(id),
    permission VARCHAR(100) NOT NULL
);

INSERT INTO roles VALUES
    (4, 'Viewer',  NULL),  -- base role, inherits nothing
    (3, 'Editor',  4),     -- extends Viewer
    (2, 'Manager', 3),     -- extends Editor
    (1, 'Admin',   2);     -- extends Manager, inherits all

INSERT INTO role_permissions VALUES
    (1, 'delete_posts'),
    (1, 'manage_users'),
    (2, 'publish_posts'),
    (3, 'edit_posts'),
    (4, 'view_posts');
Querying All Inherited Permissions
To get every permission a Manager (id = 2) has — including the ones inherited from Editor and Viewer — climb up the chain to find all ancestor roles, then join to permissions:
WITH RECURSIVE role_ancestors AS (
    -- Anchor: start with the target role
    SELECT id, name, parent_id
    FROM roles
    WHERE id = 2  -- Manager

    UNION ALL

    -- Recursive: climb UP to base roles
    SELECT r.id, r.name, r.parent_id
    FROM roles r
    INNER JOIN role_ancestors ra ON r.id = ra.parent_id
)
SELECT DISTINCT rp.permission
FROM role_ancestors ra
JOIN role_permissions rp ON rp.role_id = ra.id
ORDER BY rp.permission;
Result:
permission
-----------
edit_posts
publish_posts
view_posts
The query starts at Manager, climbs to Editor (parent_id = 3), then Viewer (parent_id = NULL) — picking up each role’s permissions along the way. The only structural difference from the category tree query is the join direction: r.id = ra.parent_id instead of c.parent_id = ct.id. That single swap flips traversal from child-finding to ancestor-finding. Everything else is identical.
Practical Tips and Gotchas
Always Index parent_id
Without an index on parent_id, each recursive step does a full table scan. With a couple thousand rows this is fine; with hundreds of thousands it becomes painful:
CREATE INDEX idx_categories_parent ON categories(parent_id);
CREATE INDEX idx_roles_parent ON roles(parent_id);
Guard Against Infinite Loops
Accidental circular references — a node whose parent chain eventually points back to itself — will make a recursive CTE loop until the database hits its recursion limit. Add a depth cap as a safety net:
WITH RECURSIVE category_tree AS (
    SELECT id, name, parent_id, 0 AS depth
    FROM categories WHERE id = 1

    UNION ALL

    SELECT c.id, c.name, c.parent_id, ct.depth + 1
    FROM categories c
    INNER JOIN category_tree ct ON c.parent_id = ct.id
    WHERE ct.depth < 20  -- stop after 20 levels
)
SELECT * FROM category_tree;
PostgreSQL 14+ also has a built-in CYCLE clause for proper cycle detection without the manual depth trick.
Seeding Test Data from Spreadsheets
When I’m setting up test hierarchies, I often start from a spreadsheet exported as CSV. When I need to quickly convert CSV to JSON for data imports, I use toolcraft.app/en/tools/data/csv-to-json — it runs entirely in the browser so no data leaves your machine. Much faster than writing a one-off conversion script for something you’ll do once.
Taking It Further
Recursive CTEs are built for queries that would otherwise mean multiple round trips to the database or unrolling tree logic in application code. The shape is consistent: an anchor that picks your starting node, a recursive member that steps one level at a time — downward to fetch descendants, or upward to collect ancestors.
The two examples here cover both directions. Category tree traversal goes down; permission inheritance climbs up. Once that core pattern is in your toolkit, most hierarchical problems reduce to “which direction do I traverse?”
When read performance needs to scale further, the Closure Table pattern is worth knowing. It pre-materializes every ancestor-descendant pair into a separate table, trading write overhead for O(1) hierarchy reads — worth it once your tree reaches tens of thousands of nodes and query load is high.