Context & Why
At 2:14 AM, PagerDuty woke me up with alert spikes from our executive reporting bot. C-suite users were asking basic questions about Q3 earnings, and the system was inventing numbers out of thin air. Looking at the trace logs, the breakdown was obvious.
Our OCR worker had mauled a three-column financial table with nested footnotes. It flattened everything into an incoherent string of raw text, which our pipeline blindly chunked and embedded into pgvector. The LLM received pure garbage context. Naturally, it hallucinated with complete confidence.
Most production RAG stacks still depend on this brittle pipeline. You extract raw PDF streams or run PaddleOCR, scrub the markdown, split text into arbitrary 500-token chunks, compute dense embeddings, and run vector search. Everything works fine until you hit complex layouts. Balance sheets lose their column coordinates. Two-column whitepapers read across columns instead of down. Charts and infographics simply vanish.
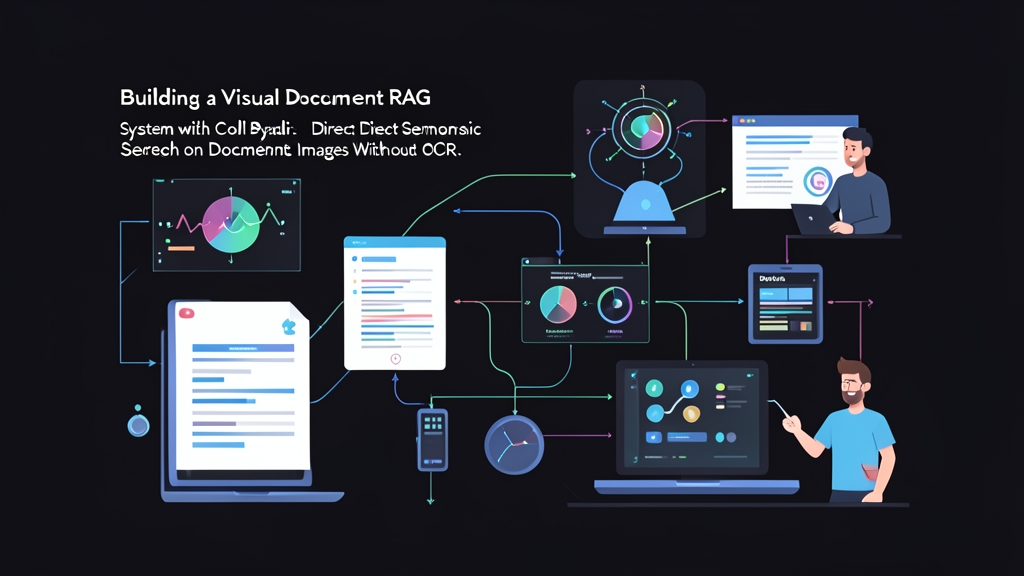
ColPali sidesteps text extraction completely. Instead of guessing layout flow, it rasterizes each PDF page into a 448×448 image and feeds it directly into a Vision-Language Model (built on PaliGemma-3B).
The model outputs multi-vector patch embeddings—roughly 1,030 vectors per page at 128 dimensions—using ColBERT-style late interaction (MaxSim). Byaldi is the Python wrapper that packages ColPali into an indexer you can run in just a few lines of code. Tables, typography, headers, and sparklines stay visually anchored where they belong.
Ditching text extractors for visual late-interaction cut our document parsing bugs to zero on 10-K filings and complex technical manuals. Here is how to get it running on your own infrastructure.
Installation
ColPali computes token representations across image patches. While inference is relatively fast, building the index requires serious GPU memory. You will need an NVIDIA card with at least 16GB of VRAM—an RTX 4090, A5000, or cloud A10G instance works well.
Start by installing system-level PDF rendering packages. Byaldi converts pages into images under the hood using pdf2image, which requires poppler-utils.
# Ubuntu / Debian setup
sudo apt-get update && sudo apt-get install -y poppler-utils libgl1-mesa-glx

# Confirm poppler binary exists
pdftoppm -v
Set up an isolated virtual environment with PyTorch and CUDA. Match your CUDA runtime to the PyTorch wheel version to prevent annoying segmentation faults during tensor operations.
# Create and activate environment
python3 -m venv venv-byaldi
source venv-byaldi/bin/activate

# Install PyTorch with CUDA 12.1 support
pip install --upgrade pip
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu121

# Install Byaldi and Flash Attention 2 for faster forward passes
pip install byaldi
pip install flash-attn --no-build-isolation
Stuck on flash-attn compilation errors? Make sure your CUDA_HOME path points to the full CUDA toolkit (e.g. /usr/local/cuda). If you run on an environment without build tools, you can skip flash-attn; PyTorch’s native SDPA will step in as a fallback.
Configuration
Byaldi handles document loading, embedding generation, and index persistence out of the box. The base checkpoint vidore/colpali-v1.2 delivers solid zero-shot accuracy across multi-lingual documents, scans, and dense reports.
Save this script as indexer.py to batch-index an entire directory of PDFs:
import os
from byaldi import RAGMultiModalModel

INDEX_NAME = "financial_reports_index"
DOCS_DIR = "/var/data/pdf_vault"

def build_document_index():
    print("[INIT] Loading ColPali model into VRAM...")
    RAG = RAGMultiModalModel.from_pretrained(
        "vidore/colpali-v1.2",
        verbose=1
    )

    print(f"[INDEX] Scanning {DOCS_DIR} and indexing pages...")
    RAG.index(
        input_path=DOCS_DIR,
        index_name=INDEX_NAME,
        store_collection_with_index=True,
        overwrite=True
    )
    print(f"[SUCCESS] Index written to .byaldi/{INDEX_NAME}")

if __name__ == "__main__":
    os.makedirs(DOCS_DIR, exist_ok=True)
    build_document_index()
After building the index, build your query service (search.py). This step queries the pre-computed vectors without reloading the original PDF documents into memory. It returns the top matching page numbers, file IDs, and full page snapshots.
from byaldi import RAGMultiModalModel

INDEX_NAME = "financial_reports_index"

def query_visual_rag(query_text: str, top_k: int = 3):
    # Load the serialized index
    RAG = RAGMultiModalModel.from_index(INDEX_NAME)

    # Run late-interaction MaxSim search
    results = RAG.search(query=query_text, k=top_k)

    print(f"\nQuery: '{query_text}'")
    print(f"Returned {len(results)} matches:\n" + "-" * 45)

    for rank, hit in enumerate(results, start=1):
        doc_id = hit.doc_id
        page_num = hit.page_num
        score = hit.score
        print(f"#{rank} | Doc: {doc_id} | Page: {page_num} | Score: {score:.3f}")

        # Tip: Send hit.base64 straight to a multimodal model like Claude 3.5 Sonnet or GPT-4o
        # page_base64 = hit.base64

    return results

if __name__ == "__main__":
    # Test query against nested table data
    query_visual_rag("What was our net operating margin across Europe in Q3 2024?")
Verification & Monitoring
Do not push visual retrieval to production without baseline benchmarks. You need to verify both search relevance and GPU stability under real traffic.
1. Validating Layout Retrieval Accuracy
Write integration tests with queries that consistently trip up standard text parsers. Good targets include cell values deep inside borderless tables, footnotes, and legend keys inside graphs.
# Measure query execution latency
python -m timeit -n 10 -s "from search import query_visual_rag" "query_visual_rag('FY2024 EBITDA margin')"
In practice, ColPali MaxSim similarity scores range from 12.0 to 28.0. Scores above 19.5 reliably indicate tight semantic and visual correspondence. If your top hits hover below 14.0, the document likely does not contain the answer, or the query needs rewording.
2. Monitoring GPU VRAM and Batch Sizing
Rasterizing high-resolution PDFs (such as 300–600 DPI scans) consumes huge chunks of GPU memory during batch ingestion. Unchecked, this leads straight to CUDA OOM panics.
Keep a terminal open to monitor VRAM consumption during ingestion:
watch -n 1 nvidia-smi --query-gpu=timestamp,utilization.gpu,memory.used,memory.total --format=csvIf memory consumption climbs past 85% on a 16GB GPU, downsample your PDF assets prior to ingestion. A quick Ghostscript pass reduces file weight while preserving legibility for PaliGemma:
# Downsample heavy 600 DPI scans to 150 DPI screen resolution
gs -sDEVICE=pdfwrite -dCompatibilityLevel=1.4 -dPDFSETTINGS=/ebook \
   -dNOPAUSE -dQUIET -dBATCH -sOutputFile=optimized_doc.pdf raw_input.pdf
3. Production Latency and Capacity Planning
Visual retrieval changes your infrastructure bottlenecks. Keep these production benchmarks in mind:
- Query Latency: Expect queries to complete within 120ms to 280ms on a single A10G. Latency spikes above 600ms usually point to CPU thread contention during matrix multiplication.
- Storage Footprint: Unlike single-vector embeddings that consume ~3KB per page, ColPali stores multi-vector representations. Expect ~25MB to 40MB of disk usage per 100 indexed pages with Byaldi’s binary/PLAID compression.
- Graceful Degradation: Wrap
RAG.search()in atorch.cuda.OutOfMemoryErrortry/except block. If VRAM runs out, clear the PyTorch cache withtorch.cuda.empty_cache()and fall back to an existing BM25 keyword index rather than failing the user request.
Visual document retrieval fixes the weakest link in modern RAG. By treating pages as visual canvases rather than flat text strings, ColPali and Byaldi deliver reliable answers from complex layouts without fragile regexes or brittle OCR jobs.