Context & Why: Scaling Beyond Single-Node Redis
Six months ago, our notification service began dropping messages during flash sales. Memory consumption on our 32 GB standalone Redis instance climbed past 28 GB (87%), while p99 latency spiked from 1.2 ms to 140 ms during write bursts. Our PostgreSQL and MongoDB clusters handled persistence without issue, but pushing 48,000 in-memory write ops per second to a single Redis process reached hardware limits.
Redis Sentinel automates failovers, yet every write command still terminates on a single primary node. When you exceed the CPU or memory ceiling of one machine, horizontal sharding is required. Redis Cluster addresses this by partitioning the keyspace across 16,384 fixed hash slots. It maps every key to an exact slot using CRC16(key) mod 16384, distributing reads and writes across multiple independent master nodes.
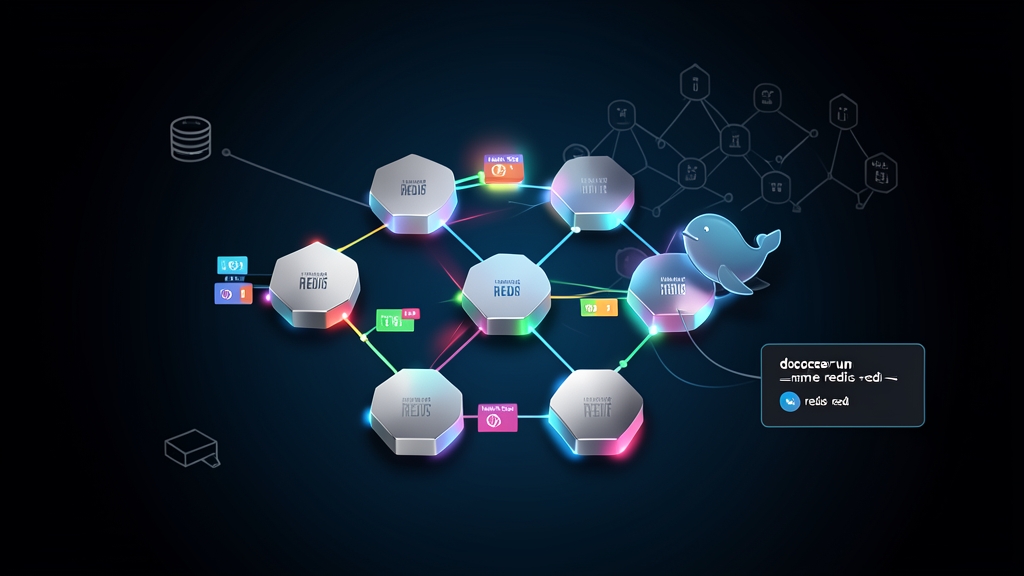
High availability comes from pairing each master with at least one dedicated replica. When a master stops answering pings, the remaining masters detect the heartbeat failure over the cluster bus. They hold an election using gossip consensus and promote a standby replica without human intervention. Emulating this six-node architecture in Docker allows you to test failover dynamics, slot migrations, and client redirects locally before touching staging clusters.
Installation: Containerized Cluster Layout
A resilient Redis Cluster needs at least three master nodes. That odd count guarantees a majority quorum during network partitions and prevents split-brain scenarios. Adding one replica per master brings the deployment to six nodes. While production clusters typically run across independent hosts, a custom Docker bridge network gives us predictable, isolated IP allocation locally.
Set up the project directory and prepare dedicated data volumes for all six nodes:
mkdir -p redis-cluster && cd redis-cluster
mkdir -p data/node-{1..6}
Save the following compose definition as docker-compose.yml:
version: '3.8'

networks:
  redis-net:
    driver: bridge
    ipam:
      config:
        - subnet: 172.28.0.0/16

services:
  redis-node-1:
    image: redis:7.2-alpine
    container_name: redis-node-1
    command: ["redis-server", "--port", "7001", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-1:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.11
    ports:
      - "7001:7001"
      - "17001:17001"

  redis-node-2:
    image: redis:7.2-alpine
    container_name: redis-node-2
    command: ["redis-server", "--port", "7002", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-2:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.12
    ports:
      - "7002:7002"
      - "17002:17002"

  redis-node-3:
    image: redis:7.2-alpine
    container_name: redis-node-3
    command: ["redis-server", "--port", "7003", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-3:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.13
    ports:
      - "7003:7003"
      - "17003:17003"

  redis-node-4:
    image: redis:7.2-alpine
    container_name: redis-node-4
    command: ["redis-server", "--port", "7004", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-4:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.14
    ports:
      - "7004:7004"
      - "17004:17004"

  redis-node-5:
    image: redis:7.2-alpine
    container_name: redis-node-5
    command: ["redis-server", "--port", "7005", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-5:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.15
    ports:
      - "7005:7005"
      - "17005:17005"

  redis-node-6:
    image: redis:7.2-alpine
    container_name: redis-node-6
    command: ["redis-server", "--port", "7006", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--cluster-node-timeout", "5000", "--appendonly", "yes", "--protected-mode", "no"]
    volumes:
      - ./data/node-6:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.16
    ports:
      - "7006:7006"
      - "17006:17006"
Notice the dual port mapping for each container. Redis listens for application traffic on ports 7001-7006, but it also allocates cluster bus communication ports on 17001-17006 (client port + 10,000). The cluster bus carries binary gossip exchanges, heartbeat pings, and failover authorization packets. If an external firewall or container network blocks those high ports, your nodes cannot form a quorum.
Start all six containers in the background:
docker compose up -d
Configuration: Initializing Slots and Network Topology
Starting the containers launches six standalone Redis instances running in cluster mode. However, they do not discover one another automatically. You must knit them into an active topology and allocate hash slots using redis-cli --cluster create:
docker exec -it redis-node-1 redis-cli --cluster create \
  172.28.0.11:7001 172.28.0.12:7002 172.28.0.13:7003 \
  172.28.0.14:7004 172.28.0.15:7005 172.28.0.16:7006 \
  --cluster-replicas 1
The --cluster-replicas 1 argument designates the first three IP addresses as primary masters and attaches one replica to each. The CLI generates a balanced slot allocation across the 16,384 available slots:
- Node 1 (172.28.0.11:7001): Slots 0 – 5460 (5,461 slots)
- Node 2 (172.28.0.12:7002): Slots 5461 – 10922 (5,462 slots)
- Node 3 (172.28.0.13:7003): Slots 10923 – 16383 (5,461 slots)
Type yes when prompted. Redis configures the epoch, binds the replicas, and returns [OK] All 16384 slots covered.
Validating Infrastructure Networks and Configs
CIDR overlaps happen frequently when juggling multiple custom Docker networks on a developer workstation. Before binding 172.28.0.0/16, verify that the range does not conflict with corporate VPN routes or Docker’s default bridge pools. You can calculate available address ranges and netmasks using the Subnet Calculator on ToolCraft. It processes everything client-side in your browser, keeping your internal infrastructure plan off third-party servers.
When porting Docker Compose definitions into Kubernetes ConfigMaps or Helm values, ensure syntax errors do not slip into deployment manifests. You can convert between structural formats with the YAML to JSON Converter or sanity-check complex parameters using the JSON Formatter & Validator.
Verification & Monitoring: Slot Routing and Failover Testing
Verify that your topology converged properly by querying any node with redis-cli. Always include the -c flag to activate cluster routing:
docker exec -it redis-node-1 redis-cli -p 7001 -c cluster nodes
The console output prints a 40-character hexadecimal node ID, current role (master or slave), ping/pong state, and the slot range served by each master.
Testing Automatic Slot Redirection
Standard Redis clients throw a MOVED error when a command targets a key stored on a different node. Adding -c instructs the client to catch that signal and follow the redirect. Open a session on Node 1 and write two distinct keys:
docker exec -it redis-node-1 redis-cli -p 7001 -c

127.0.0.1:7001> SET user:alpha "session_payload_1"
-> Redirected to slot [14674] located at 172.28.0.13:7003
OK
172.28.0.13:7003> SET user:beta "session_payload_2"
-> Redirected to slot [9382] located at 172.28.0.12:7002
OK
172.28.0.12:7002> GET user:alpha
-> Redirected to slot [14674] located at 172.28.0.13:7003
"session_payload_1"
Observe the client output. Writing user:alpha maps to slot 14674 on Node 3, while user:beta falls into slot 9382 on Node 2. The client jumps across master nodes in less than a millisecond, abstracting the partitioned layout from the caller.
Simulating Master Failure and Node Failover
High availability claims mean nothing until you terminate an active primary. Stop redis-node-1, which currently holds slots 0 to 5,460:
docker stop redis-node-1
Follow the election process in the logs of its assigned replica (typically redis-node-4 or redis-node-5, as assigned during cluster creation):
docker logs -f redis-node-4
Within 5 seconds (matching our cluster-node-timeout), the replica detects the missing master and claims the slot range:
* Marking node 172.28.0.11:7001 as failed (FAIL).
* Starting a failover election for epoch 2.
* Failover election won: I am the new master.
* Configuration epoch set to 2.
* Clearing my fail state and serving slots 0 - 5460.
Query the cluster state from surviving Node 2 to inspect the new layout:
docker exec -it redis-node-2 redis-cli -p 7002 -c cluster nodes
Node 4 now shows the master flag, serving slots 0–5460 without data loss. Restart the dead container with docker start redis-node-1. Once back online, Node 1 discovers that Node 4 took over its hash slots, demoting itself to a replica cleanly.
Production Takeaways After 6 Months
Operating a sharded cluster under load revealed several critical operational details:
- Force Hash Slot Affinity for Multi-Key Commands: Multi-key operations such as
MGET, pipeline transactions, and Lua scripts fail with aCROSSSLOTerror if target keys sit on different masters. Enforce slot locality by wrapping common prefixes in curly braces:{tenant:101}:profileand{tenant:101}:ordershash only the string inside{...}, binding them to the same master. - Calibrate
cluster-node-timeoutRealistically: The default timeout of 15,000 ms leaves an application waiting 15 seconds before failover completes. We dialed this down to 5,000 ms for staging. However, avoid setting this under 2,000 ms in production, as standard Java or Node.js garbage collection pauses can cause split-second false positives and trigger unnecessary failovers. - Rely on Cluster-Aware Drivers: Always use libraries that maintain an in-memory slot map, such as Lettuce (Java),
redis-pywithRedisCluster(Python), orioredis(Node.js). Drivers without cluster topology caching execute an extraMOVEDnetwork trip on every single mismatched query, instantly doubling your round-trip latency.