Quick Start: Stopping the 2 AM Connection Spike
Your monitoring fires an alert at 2 AM. API p99 latency just jumped from 45ms to 12,000ms. In the logs, you see the dreaded message: FATAL: remaining connection slots are reserved for non-replication superuser connections.
Your PostgreSQL instance slammed into its max_connections ceiling. Because each backend worker process consumes between 5MB and 10MB of baseline RAM, your server is paging to disk. Queries are stalling across every service.
Resist the urge to simply double max_connections in postgresql.conf. Raising it from 100 to 1,000 invites the Linux Out-Of-Memory (OOM) killer to terminate your database process under load. Placing PgBouncer in front of PostgreSQL acts as a pressure valve, stabilizing memory and latency within minutes.
1. Install PgBouncer
# Debian / Ubuntu
sudo apt-get update && sudo apt-get install -y pgbouncer

# RHEL / Rocky Linux
sudo dnf install -y pgbouncer
2. Minimal Production Configuration
Open /etc/pgbouncer/pgbouncer.ini and configure a lightweight proxy:
[databases]
# Route incoming app traffic to PostgreSQL on localhost
app_production = host=127.0.0.1 port=5432 dbname=app_production

[pgbouncer]
listen_addr = 0.0.0.0
listen_port = 6432
auth_type = scram-sha-256
auth_file = /etc/pgbouncer/userlist.txt
admin_users = postgres, pgbouncer_admin

# Pooling parameters
pool_mode = transaction
max_client_conn = 5000
default_pool_size = 25
reserve_pool_size = 5
reserve_pool_timeout = 5
3. Configure Credentials and Start the Service
PgBouncer verifies user credentials against a local lookup file. You can extract your existing user record directly from PostgreSQL:
sudo -u postgres psql -d app_production -Atc \
  "SELECT concat('"', usename, '" "', passwd, '"') FROM pg_shadow WHERE usename = 'app_user';" \
  | sudo tee -a /etc/pgbouncer/userlist.txt
Restrict file permissions and enable the daemon:
sudo chown -R postgres:postgres /etc/pgbouncer
sudo chmod 0600 /etc/pgbouncer/userlist.txt
sudo systemctl restart pgbouncer
Switch your application’s database port from 5432 to 6432. 5,000 incoming app connections now queue gracefully into a steady pool of 25 backend workers. Latency drops back to normal immediately.
Deep Dive: Why PostgreSQL Falls Over Under Heavy Concurrency
PostgreSQL relies on a process-per-connection architecture rather than threads. Every client socket causes the OS to fork a dedicated postgres process.
This creates two major bottlenecks at scale:
- Memory bloat: 600 client connections allocate roughly 4GB to 6GB of RAM just to maintain socket buffers and per-process catalogs. That memory is lost before queries even allocate
work_memfor hash joins or sorting. - CPU context switching: With hundreds of processes contending for 8 or 16 CPU cores, the Linux kernel spends more CPU cycles swapping process state than executing SQL.
Choosing the Right Pool Mode
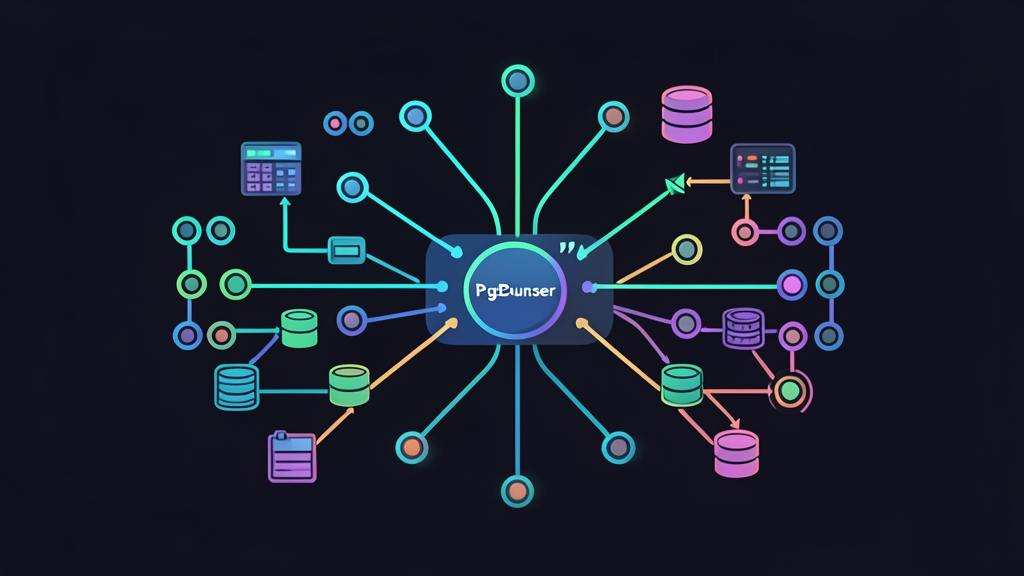
PgBouncer sits between your applications and Postgres, acting as an intelligent connection multiplexer. It operates in three distinct pooling modes:
- Session Pooling: PgBouncer ties a server connection to a client the moment it logs in and holds it until disconnect. It supports 100% of Postgres features, including temporary tables and session locks. However, it provides almost zero concurrency gains when thousands of clients idle simultaneously.
- Transaction Pooling (Recommended): PgBouncer borrows a database connection only for the duration of a transaction (
BEGIN ... COMMIT). The instant the transaction finishes, PgBouncer hands that backend worker to the next client in line. Thousands of web clients can easily share 25 to 50 active PostgreSQL processes. Note: session-level state changes (such asSET timezone) do not persist across queries. - Statement Pooling: Connections return to the pool after every individual query. Multi-statement transactions are forbidden. Use this mode only for pure key-value lookups or auto-commit analytics feeds.
The Query Pipeline in Action
Under transaction pooling, client requests flow through four explicit stages:
- The client opens a long-lived TCP socket to PgBouncer on port
6432. - If all 25 PostgreSQL connections are busy, PgBouncer holds the client in an in-memory queue.
- The moment a backend connection finishes a transaction, PgBouncer assigns it to the waiting client.
- Postgres executes the query, returns the result set, and PgBouncer immediately claims the connection back.
Tuning for Multi-Tenant and Production Workloads
A single misbehaved batch job or unindexed query can monopolize every pooled connection. You need granular routing to guard against connection starvation.
Splitting Workloads Across Dedicated Pools
Isolate latency-sensitive user API calls from batch workers by defining virtual databases inside /etc/pgbouncer/pgbouncer.ini:
[databases]
# High-priority REST API traffic
app_live = host=127.0.0.1 port=5432 dbname=app_production pool_mode=transaction pool_size=40

# Long-running background jobs using session pooling
app_analytics = host=127.0.0.1 port=5432 dbname=app_production pool_mode=session pool_size=5

[users]
# Restrict automated reporting scripts
report_bot = pool_mode=transaction max_user_connections=5
Handling Prepared Statements in PgBouncer 1.21+
Because transaction pooling swaps server connections between queries, prepared statements historically triggered errors like prepared statement "s1" does not exist. Modern ORMs (including Prisma, ActiveRecord, and SQLAlchemy) often turn them on by default.
Starting with PgBouncer 1.21, you can enable transparent protocol-level prepared statements:
[pgbouncer]
max_prepared_statements = 100
If you run older PgBouncer releases, disable prepared statements in your ORM config (for example, setting pgbouncer=true in a Prisma connection string or prepare_threshold: nil in ActiveRecord).
Inspecting Real-Time Pool Metrics
PgBouncer includes an internal administration console accessible via psql:
psql -p 6432 -U pgbouncer_admin -d pgbouncerKey diagnostic commands to run during traffic spikes:
-- Monitor client queue depth vs. idle servers
SHOW POOLS;

-- Inspect connected clients and current transaction state
SHOW CLIENTS;

-- Track query volume, data transfer, and wait times
SHOW STATS;
Watch the cl_waiting column in SHOW POOLS. If cl_waiting stays above 0 while sv_idle remains at 0 for extended periods, increase default_pool_size in increments of 5 to 10.
Production Field Lessons
1. Match Pool Size to CPU Core Limits
Setting default_pool_size = 500 on an 8-core machine creates severe lock contention. More connections rarely mean more throughput. A proven heuristic for sizing active backends is:
Max Active Backends = ((CPU_cores * 2) + effective_spindle_count)For a dedicated 16-core database server with fast NVMe storage, 35 to 50 active PostgreSQL processes yield lower p99 latency than 400 unmanaged connections fighting over memory and L3 cache lines.
2. Sanitizing Imported Payloads Safely
Hotfixes and emergency database patches often require mass data uploads or payload audits. When converting CSV dumps to JSON before running targeted batch updates, use an in-browser utility like toolcraft.app/en/tools/data/csv-to-json. Because the parsing runs purely in local WebAssembly, sensitive customer PII never leaves your browser, preventing data leaks during manual migration steps.
3. Essential Timeouts and File Descriptor Limits
Prevent orphaned sockets from silently exhausting OS resources:
server_idle_timeout = 600: Closes server connections that have sat idle for 10 minutes, returning memory to the OS.query_timeout = 30: Aborts queries that hang longer than 30 seconds, protecting backend workers from runaway sequential scans.- File descriptor limits: PgBouncer manages thousands of concurrent sockets. Add the following lines to
/etc/security/limits.conf:
postgres soft nofile 65536
postgres hard nofile 65536
Apply the change with sysctl -p, ensuring the daemon handles traffic surges without hitting OS descriptor exhaustion.